Back
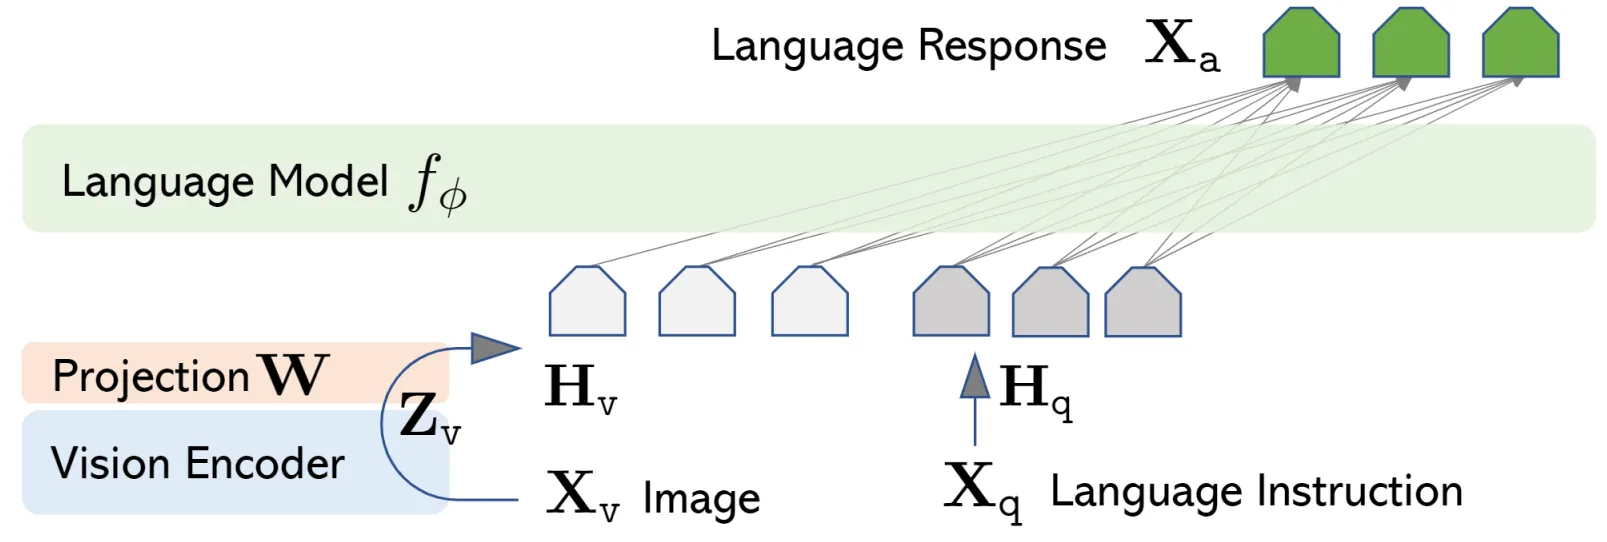
把视觉表示接入 LLM,再用纯文本大模型构造视觉对话数据
paper-reading
llava
multimodal
instruction-tuning
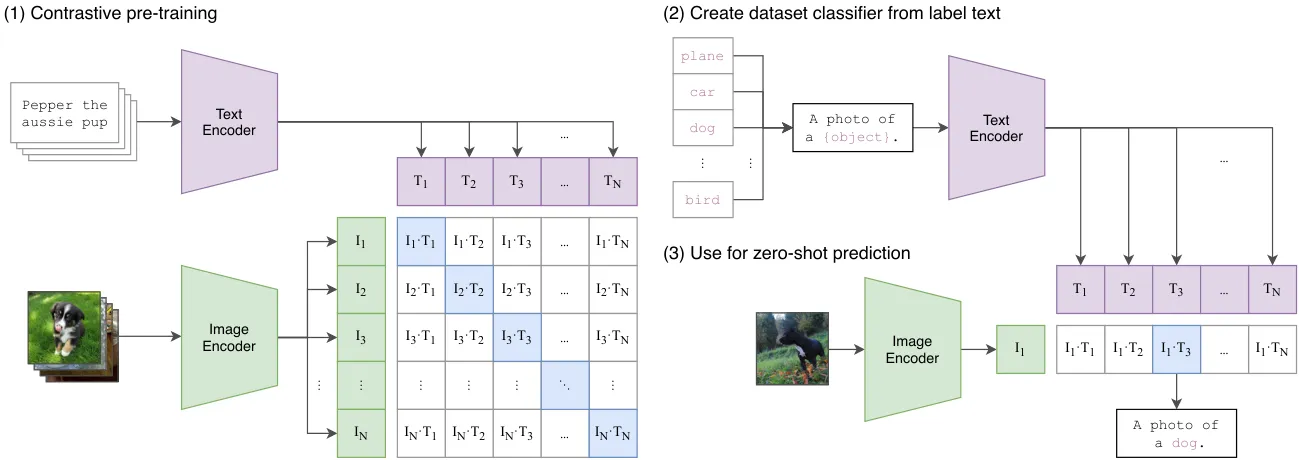
用对比学习对齐图像和文本,再用自然语言构造 zero-shot 分类器
clip
contrastive-learning